In many manufacturing plants, Overall Equipment Effectiveness (OEE) has become one of the most visible indicators of operational performance.
It appears on production dashboards, daily management boards, shift reports, and management reviews.
A low OEE triggers concern. A rising OEE suggests improvement. A high OEE is frequently interpreted as evidence of operational excellence.
But an important question remains:
What happens when an organization improves its OEE without understanding the losses behind it?
The factory may report better performance while continuing to experience recurring equipment failures, unstable processes, quality problems, and production constraints.
Sometimes the indicator improves because the underlying process has genuinely improved.
Sometimes it improves because the measurement rules have changed.
And in certain circumstances, pursuing higher equipment OEE can encourage decisions that undermine the performance of the manufacturing system as a whole.
OEE itself is not the problem.
The problem begins when OEE stops being a mechanism for understanding and reducing losses and becomes a number that the organization is expected to defend.
A Good Number Can Hide a Bad Process
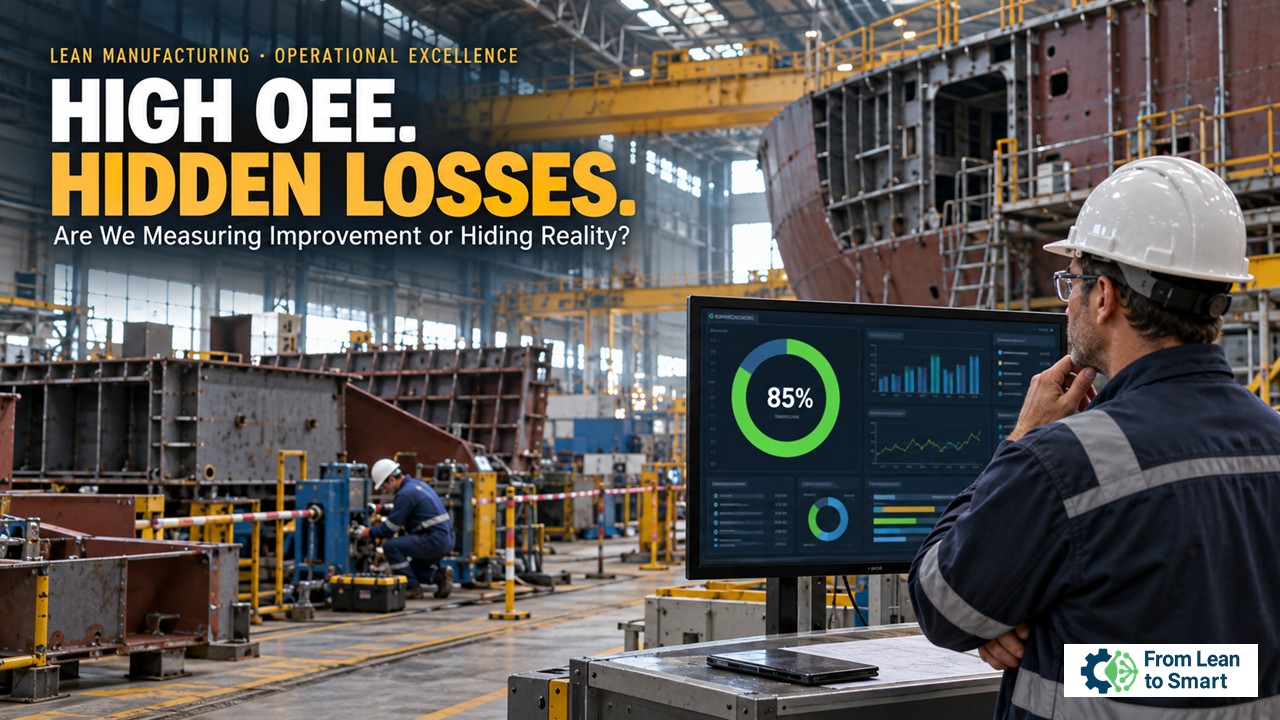
Consider an automotive assembly line reporting an OEE of 85%.
At first glance, management may regard the result as satisfactory, particularly if it aligns with an established internal target.
However, 85% is not a universal threshold for operational excellence. Its interpretation depends on the production process, measurement conventions, operating conditions, and purpose of the assessment.
More importantly, the percentage alone provides limited information about the underlying losses.
One line may lose productive capacity through frequent microstoppages associated with equipment instability.
Another may maintain high availability while consistently operating below its intended production rate.
A third may operate close to nominal speed while generating nonconforming units or requiring substantial rework.
These different situations can produce similar OEE values.
Yet they require different technical and managerial responses.
Maintenance may need to investigate recurring mechanical failures or equipment degradation.
Engineering may need to examine process capability, equipment limitations, or cycle-time stability.
Production may need to improve changeovers, operating standards, or abnormality response.
Quality may need to address recurring process deviations and their underlying mechanisms.
The indicator identifies a performance gap.
It does not establish its cause.
OEE becomes valuable when it helps the organization identify where productive capacity is being lost, understand why those losses occur, and decide which improvements are justified.
Without that connection, the percentage can create an illusion of operational control.
The Difference Between Measuring Performance and Understanding Losses
OEE combines three dimensions:
OEE = Availability × Performance × Quality
This structure is useful because it recognizes that manufacturing effectiveness depends on more than equipment breakdowns.
Availability represents the proportion of planned production time during which the equipment is operating.
Performance compares actual production with the output expected during operating time under the defined ideal cycle-time convention.
Quality represents the proportion of produced units meeting the applicable quality criteria.
The calculation is straightforward in principle.
Its operational interpretation is not.
Consider the measurement of Availability.
Does a material shortage count as equipment downtime within planned production time?
How is a missing operator classified?
What happens when a machine stops because a downstream process cannot accept additional material?
Are changeovers included in planned production time?
Which preventive maintenance periods are excluded, and on what basis?
These questions must be resolved through an explicit measurement policy.
They cannot be answered solely by choosing a software configuration.
Different measurement conventions may be appropriate for different analytical purposes. However, the boundaries, exclusions, and classification rules must remain transparent and sufficiently stable to support meaningful comparison.
Particular care is required when reported performance is compared over time.
If planned production time is redefined, operating periods are excluded, or the ideal cycle time is modified, the reported OEE may change even when the physical production process remains unchanged.
This does not mean that measurement standards must never be revised.
It means that revisions should be technically justified, documented, and distinguished from genuine operational improvement.
A mathematically correct OEE calculation can still be misleading when its measurement boundaries are misunderstood or ignored.
If the objective is to understand equipment-related losses, the classification should support that purpose.
If the objective is to evaluate manufacturing throughput, delivery performance, or overall capacity constraints, additional indicators are required.
OEE provides a specific perspective on manufacturing performance.
It should not be treated as a complete representation of the operating system.
When the Measurement System Starts Influencing Behavior
Performance indicators do more than describe operational conditions.
They influence decisions and behavior.
Once OEE becomes a management target, the organization naturally pays closer attention to the rules used to calculate it.
This is not inherently negative. Well-designed targets can direct attention toward relevant improvement opportunities.
However, poorly governed targets may encourage unintended behavior.
Consider a production team experiencing recurring interruptions because the required material is unavailable.
If these interruptions reduce its reported OEE, the team may argue that material shortages should be excluded because they fall outside its direct responsibility.
Maintenance may make a similar argument about interruptions caused by production adjustments.
Planning may consider certain idle periods unavoidable.
Each function may have a legitimate concern about accountability.
However, responsibility for a loss and visibility of that loss are different matters.
An organization can distinguish equipment failures, material shortages, production restrictions, and planned interruptions without making inconvenient losses disappear from operational analysis.
The danger arises when departments negotiate measurement exclusions primarily to protect their reported performance.
The factory may eventually achieve a higher OEE while the underlying interruptions remain unchanged.
The indicator has improved.
The operation has not.
A mature manufacturing organization should be capable of distinguishing improvements in measurement quality from improvements in physical performance.
The integrity of the indicator depends on preserving visibility of relevant losses, even when their causes lie outside the immediate responsibility of the team being measured.
A Practical Example: The Hidden Cost of Microstoppages
Consider an automated assembly station experiencing frequent short interruptions.
Most events last only a few seconds.
Operators restore normal operation quickly, and production continues.
Because the interruptions are brief, they may not initially attract the same attention as major equipment breakdowns.
The daily report shows relatively high equipment availability.
However, the station repeatedly fails to maintain its intended production rate.
The accumulated effect of short interruptions reduces productive output.
Depending on the measurement convention, these events may be classified as Performance losses or recorded as Availability losses when their duration exceeds an established threshold.
The classification matters for reporting consistency.
But the operational problem exists independently of the category assigned to it.
The organization could respond by adjusting the ideal cycle time, modifying the threshold used to classify stops, or accepting a lower practical production rate.
Such adjustments may sometimes be justified after technical validation.
However, they should not become substitutes for understanding the loss mechanism.
A structured investigation might identify several hypotheses.
Component positioning may be inconsistent.
A sensor may be affected by contamination.
Mechanical wear may be increasing process variability.
Upstream material presentation may be creating intermittent disturbances.
The actual mechanism requires evidence.
Equipment events, operator observations, maintenance history, production conditions, and direct shopfloor analysis can help distinguish these possibilities.
Once the relevant causes have been established, the organization can select appropriate countermeasures.
The solution may involve a mechanical modification, improved material presentation, revised cleaning or inspection practices, or changes to an operating standard.
Effectiveness should then be verified under representative production conditions.
The critical improvement is not the reassignment of a loss category.
It is the demonstrated reduction of the mechanism responsible for the interruption.
This is where OEE connects with Total Productive Maintenance (TPM), structured problem-solving, and reliability engineering: the indicator identifies a loss, but technical investigation and disciplined execution are required to eliminate it.
OEE Is Not the Same as Manufacturing Flow
One of the most significant risks arises when local equipment OEE becomes more important than overall manufacturing performance.
A production system is not simply a collection of independent machines.
Its performance depends on the interaction of equipment, materials, personnel, process constraints, and customer demand.
An individual machine can achieve excellent OEE while contributing to inefficient system behavior.
Consider a non-bottleneck machine operating at high utilization to maximize its local indicator.
If its production exceeds the requirements of the downstream process, work-in-process inventory may increase.
Additional material handling may become necessary.
Production sequencing may become more complicated.
Operational problems can become less visible as buffers absorb local instability.
The machine appears productive.
The value stream becomes less effective.
This is a familiar form of local optimization.
From a Lean perspective, the relevant question is not whether every resource is producing as much as possible.
It is whether resources are operating in a manner that supports flow, quality, delivery, and the actual system constraint.
The distinction between bottleneck and non-bottleneck resources is particularly important.
At a genuine system constraint, avoidable capacity losses may directly limit throughput.
At a non-bottleneck resource, increasing utilization does not necessarily increase finished output.
Depending on the production system, it may simply generate unnecessary inventory or additional coordination costs.
This does not make OEE irrelevant outside bottleneck operations.
Understanding equipment losses remains useful for reliability, capacity planning, and continuous improvement.
However, decisions about local efficiency should be evaluated against their consequences for the overall manufacturing system.
Maximizing OEE at every workstation is not equivalent to maximizing manufacturing performance.
A mature organization understands where productive capacity is strategically important, where controlled spare capacity is necessary, and how local operating decisions influence system throughput.
Why Downtime Reason Codes Matter More Than Another Dashboard
Modern MES/MOM platforms can automate much of the OEE calculation.
Equipment signals provide machine-state information.
Production counters provide output quantities.
Quality records contribute conformity information.
Dashboards consolidate Availability, Performance, and Quality into accessible indicators.
These capabilities can improve visibility and reduce manual reporting effort.
However, automated measurement does not guarantee accurate loss interpretation.
An equipment signal may indicate that a machine has stopped.
It does not necessarily explain why.
The interruption may involve a mechanical failure, material shortage, process adjustment, quality verification, or downstream constraint.
The automation system may detect the physical state without having access to the wider operational context.
This creates an important distinction between observed equipment events and interpreted loss causes.
A stopped-state signal is evidence that the equipment was not operating.
A downtime reason code is a classification of the event.
A confirmed failure mechanism requires additional investigation.
Treating these as equivalent can weaken the quality of operational analysis.
If reason codes are too generic, Pareto analysis may provide little guidance.
If the classification is excessively detailed, operators may struggle to apply it consistently.
If categories are primarily designed around departmental responsibility, classification can become a negotiation over accountability.
A useful loss model should be understandable, sufficiently precise, consistently applied, and relevant to the decisions it supports.
It should also provide a way to distinguish confirmed causes from provisional classifications when the available information is incomplete.
The objective is not to develop the most elaborate downtime taxonomy.
It is to establish reliable information that helps identify recurring losses and direct investigation toward the relevant mechanisms.
This requires cooperation between production, maintenance, engineering, quality, and the teams responsible for MES/MOM configuration.
A sophisticated dashboard cannot compensate for a loss model that does not accurately represent manufacturing reality.
Daily Management Should Investigate Losses, Not Defend Numbers
An effective OEE measurement system is only part of the solution.
The daily management process determines whether information becomes operational improvement.
In some factories, the daily meeting follows a familiar sequence.
Yesterday’s OEE was below target.
The responsible team explains the result.
Management requests corrective actions.
The meeting moves to the next indicator.
The performance gap has been reviewed, but the relevant loss mechanism may remain insufficiently understood.
A more effective discussion begins with the losses that matter.
Which interruptions or speed losses reduced productive capacity?
Are they isolated events or recurring patterns?
Have operating conditions, product mix, material presentation, or equipment behavior changed?
Is the underlying mechanism already known?
What evidence is available?
Who is responsible for the investigation?
What decision or support is required beyond the immediate team?
These questions shift attention from defending the result toward understanding the operating conditions that produced it.
Not every loss can or should be resolved during a shift meeting.
Some require immediate containment.
Others require maintenance analysis, engineering validation, or a structured improvement activity.
The daily management process should identify the appropriate response, establish accountability, and make unresolved issues visible.
It should also review whether implemented countermeasures have produced the intended effect.
For example, if a recurring microstoppage has been addressed through equipment modification, the organization should verify whether the event frequency, accumulated loss, or associated performance instability has changed.
Completing the modification is not equivalent to demonstrating its effectiveness.
A daily OEE review creates value when it converts relevant loss information into accountable investigation, corrective decisions, and verified improvement.
Without that progression, the dashboard remains primarily a reporting mechanism.
OEE, TPM, and the Discipline of Equipment Improvement
TPM provides an important operational context for the effective use of OEE.
Within a TPM-oriented organization, the purpose of OEE is not simply to make equipment losses visible as a percentage.
It is to support the systematic identification, investigation, and reduction of losses affecting equipment effectiveness.
This requires cooperation between operators, maintenance technicians, engineers, and production leadership.
Operators often recognize abnormal equipment behavior before it develops into a major interruption.
Maintenance can relate recurring symptoms to physical deterioration, equipment condition, and failure mechanisms.
Engineering can evaluate equipment-design limitations, process capability, or technical operating standards.
Production can clarify how product changes, operating conditions, and material variation affect equipment behavior.
These perspectives are complementary.
Their value depends on disciplined problem-solving and the ability to convert observations into lasting changes.
Repeated microstoppages should not become accepted operating conditions merely because operators have become effective at recovering from them.
Chronic speed losses should not automatically disappear through revised cycle-time assumptions.
Similarly, preventive maintenance tasks should not be added without examining whether they address the relevant failure mechanism.
An appropriate countermeasure may require revised inspection practices, improved equipment design, better operating conditions, or a change in maintenance strategy.
Standards provide the baseline against which losses and abnormalities can be assessed.
Changing a standard may be justified when the original assumption is no longer valid.
But such changes should follow appropriate investigation and technical validation.
Otherwise, the organization risks gradually normalizing deteriorating equipment performance.
The objective of TPM is not to protect a performance percentage. It is to strengthen the conditions that allow equipment to operate reliably and predictably.
The Risk of Comparing OEE Without Understanding Context
OEE comparisons between factories and production lines can support organizational learning.
They may reveal performance differences and identify opportunities for further investigation.
However, comparisons become misleading when operating conditions and measurement conventions are not sufficiently understood.
Product mix, changeover frequency, equipment technology, process maturity, production scheduling, quality requirements, and operating standards can all influence reported OEE.
A high-volume production line manufacturing standardized products may face different constraints from a flexible assembly operation producing numerous variants.
Comparing their OEE percentages without considering these differences can produce unsupported conclusions.
The same problem exists within a single plant.
A system constraint, a redundant resource, and a flexible manufacturing cell may require different performance strategies.
Their contribution to overall manufacturing results cannot be assessed through local OEE alone.
A broader evaluation may need to consider throughput, lead time, schedule attainment, first-pass yield, work-in-process inventory, equipment reliability, and production cost.
These indicators provide complementary perspectives.
The purpose is not to create an unnecessarily complex performance-management system.
It is to avoid treating one measurement as a sufficient explanation of industrial performance.
OEE becomes most useful when its results are interpreted alongside the operational context and system-level objectives they are intended to support.
From OEE Reporting to Loss Intelligence
Industrial digitalization creates opportunities to strengthen the connection between OEE, operational evidence, and improvement decisions.
MES/MOM, historians, maintenance systems, and analytical platforms can help associate losses with relevant manufacturing context.
An interruption may be linked to the affected equipment, production order, product variant, maintenance history, and process conditions.
Recurring events can be examined across shifts, products, and assets.
Loss patterns can be compared with interventions and operating changes.
Process mining may help identify delays, repeated approvals, or handover weaknesses in the processes used to respond to operational problems.
Industrial AI may assist with anomaly detection, event classification, or identifying patterns that deserve investigation.
However, these capabilities introduce analytical possibilities rather than automatic causal understanding.
A model may identify that interruptions occur more frequently after certain changeovers.
This observation does not establish the mechanism responsible.
An automated system may propose a downtime category.
That classification may require validation when the evidence is ambiguous.
An analytical platform may estimate the significance of a recurring loss.
The organization must still determine whether intervention is technically justified, economically proportionate, and operationally feasible.
The transition from reporting to loss intelligence therefore requires more than additional software.
It requires a reliable information model, adequate operational context, disciplined investigation, and accountable decisions.
A useful progression is to connect five activities:
Observe the loss. Classify it consistently. Investigate its mechanism. Implement the appropriate response. Verify the outcome.
Each activity contributes something different.
Skipping the investigation can produce ineffective countermeasures.
Skipping verification can leave the organization unable to distinguish genuine improvement from temporary variation or measurement changes.
The value of digital systems lies in strengthening this sequence.
The most valuable OEE system is not necessarily the one that calculates the indicator most frequently. It is the one that helps the organization understand and control the losses that matter.
Leadership Must Protect the Integrity of the Indicator
Every performance-management system creates incentives.
Leadership therefore has a direct responsibility for how OEE is interpreted and used.
If employees are evaluated almost exclusively against an OEE target, they may become reluctant to expose losses that negatively affect reported performance.
If every low result produces pressure without adequate investigation, meetings can become defensive.
If departments operate under conflicting local targets, they may optimize their own indicators at the expense of overall manufacturing performance.
Leaders must protect the integrity of operational information.
Relevant losses should remain visible.
Calculation rules should be transparent and consistently applied.
Changes in definitions should be documented and technically justified.
Teams should distinguish improvements in reporting accuracy from reductions in actual losses.
And corrective actions should be evaluated through effectiveness, not merely administrative completion.
This does not mean eliminating performance targets.
Targets can provide direction, support prioritization, and reveal deviations from expectations.
However, they should encourage investigation and disciplined improvement rather than create incentives to exclude inconvenient information.
The organization must also recognize that individual departments do not always control the conditions responsible for their reported losses.
A production team cannot independently resolve every maintenance, material-supply, engineering, or planning constraint.
This is why loss visibility and improvement accountability should be connected through appropriate cross-functional governance.
Leadership should not reward the appearance of performance at the expense of the information required to improve it.
The objective is to establish conditions in which operational problems can be made visible, investigated, and addressed without weakening accountability.
What a More Mature Approach Looks Like
An organization using OEE as an improvement mechanism should be able to answer several practical questions.
Are Availability, Performance, and Quality calculated using documented and stable definitions?
Can the team explain the dominant losses behind the reported percentage?
Are recurring microstoppages, speed losses, and quality problems investigated rather than absorbed into revised measurement assumptions?
Can changes in OEE be separated into actual operational improvements and changes in calculation or classification?
Does the organization distinguish local equipment effectiveness from manufacturing flow and constraint performance?
Do production, maintenance, quality, and engineering have clear responsibilities for investigating relevant losses?
Does daily management convert important findings into decisions with accountable owners?
Are countermeasures verified under representative operating conditions?
And can the organization demonstrate that a reported improvement reflects an actual change in the physical or operational mechanisms affecting performance?
These questions distinguish performance reporting from performance management.
They also provide a more meaningful basis for assessing OEE maturity than dashboard sophistication or the achievement of a particular percentage.
The Real Purpose of OEE
OEE remains a valuable manufacturing performance indicator when it is used with clear definitions and an understanding of its limitations.
It can expose productive-capacity losses.
It can support TPM, reliability improvement, and structured problem-solving.
It can strengthen collaboration between production, maintenance, quality, and engineering.
And it can provide meaningful information for more advanced digital manufacturing capabilities.
But it cannot substitute for understanding the process.
A rising OEE does not necessarily demonstrate greater equipment reliability.
A high OEE does not automatically establish that material flow or system throughput has improved.
And a sophisticated reporting platform does not prove that the organization is eliminating the causes of its losses.
The essential objective is to understand the physical, operational, and organizational conditions preventing the manufacturing system from performing as intended.
That requires measurement integrity, technical investigation, appropriate decisions, and verified countermeasures.
OEE should initiate the investigation of losses, not terminate the discussion about performance.
The greatest risk is not necessarily reporting a low OEE.
It is reporting a satisfactory OEE while recurring losses, unstable processes, and counterproductive operating decisions remain hidden behind the indicator.
Questions for Further Reflection
- When our OEE improves, can we demonstrate that the underlying loss mechanisms have changed, rather than merely the calculation or classification rules?
- Are we using equipment OEE in a way that supports manufacturing flow and system constraints, or are we encouraging local optimization?
- Do our daily management routines transform loss information into investigated causes and verified countermeasures, or primarily into explanations for missed targets?
#OEE #TPM #LeanManufacturing #OperationalExcellence #ManufacturingExcellence #IndustrialMaintenance #MES #ReliabilityEngineering #ContinuousImprovement #SmartFactory